
Rigorous trainer selection
Each trainer is validated on three criteria: hands-on field expertise, proven pedagogy and alignment with your industry.
- Triple validation: technical, pedagogical, sectoral.
- Minimum rating 4.8/5 over the last 12 sessions.

Describe your need, get a tailored program and a pre-filled quote in 3 min. A 100% free call with an advisor.

1 seat held for the next session
Request a call back and an advisor reaches you within 24 business hours, Monday to Saturday.
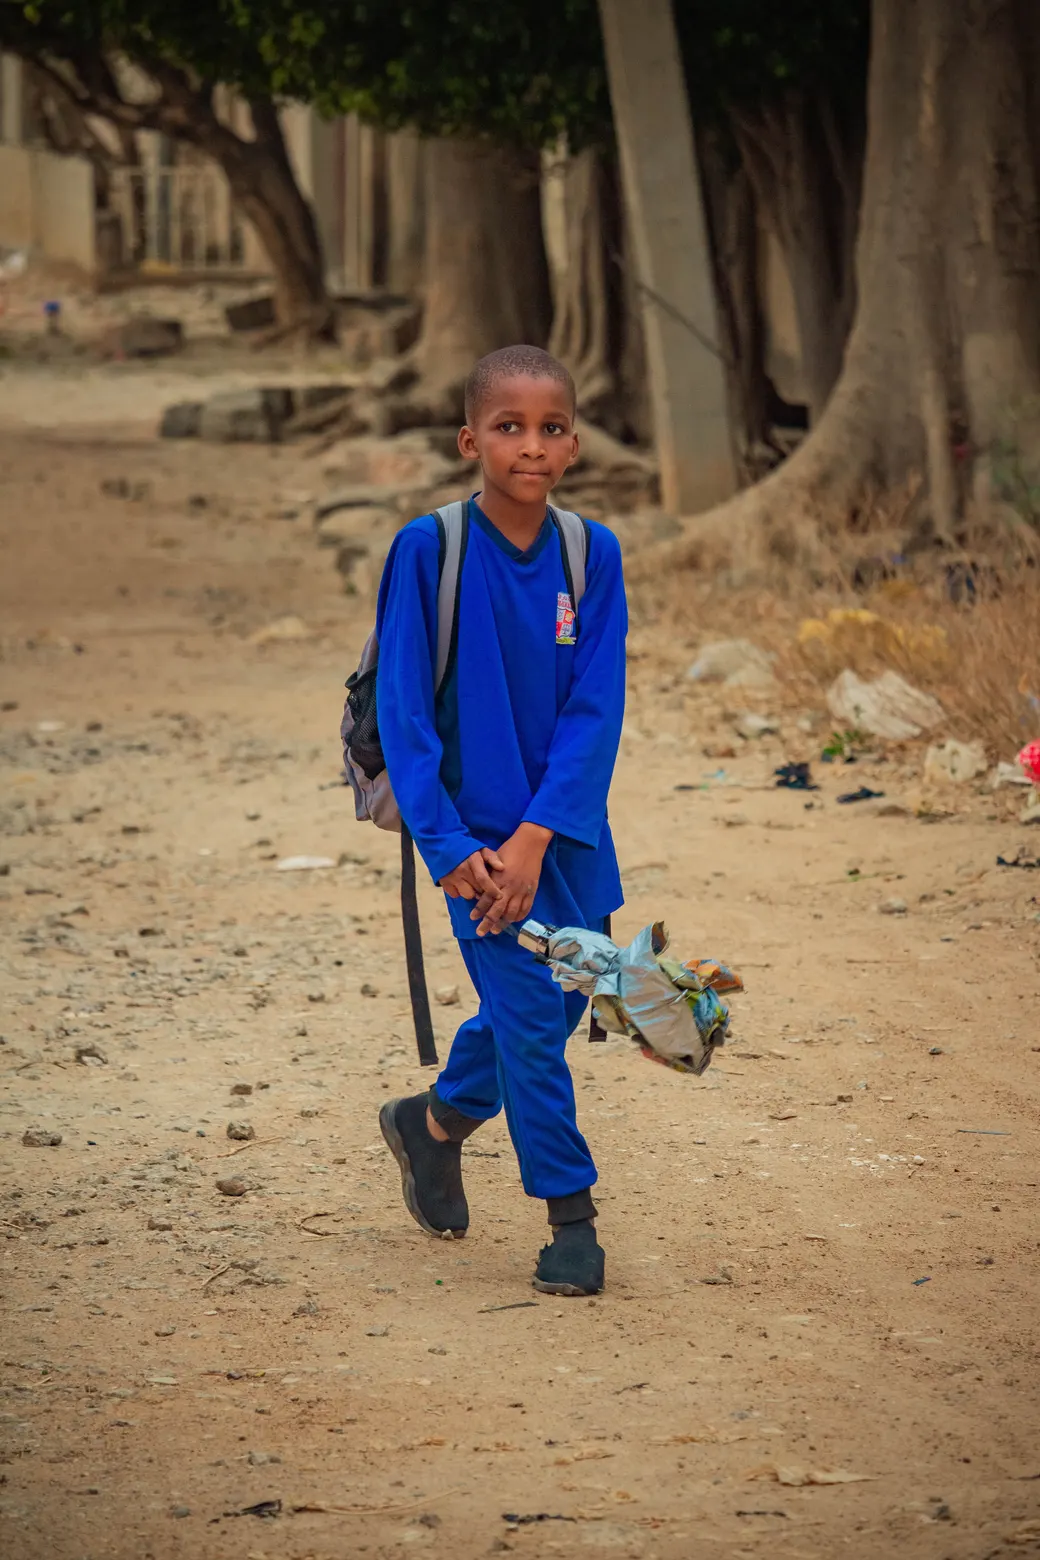
To fight inequalities in access to education, Learni donates a complete school kit to a child in need for every training booked. You build your skills, a child heads back to school.
Founded by engineers and learning experts, Learni's mission is to make high-impact tech training accessible to teams everywhere. We work remotely with organizations across the US and Canada, in your time zone, to help teams upskill fast.
Don't let this gap widen
Without prompt caching, your LLM calls cost 5 to 10 times more in tokens, with latencies multiplied by 3 exceeding 2 seconds per request.
Companies neglecting this optimization lose 40% of their AI budget annually, according to Gartner 2024, and see 25% user drop-offs due to slowness.
For teams, 68% of AI recruiters reject profiles without advanced optimization skills, risking competitive lag.
Master it to cut your costs by 4 and boost scalability starting tomorrow.
Dive into the advanced principles of prompt caching, analyze repetitive prompt structures in your AI workflows, configure tools like OpenAI API with SHA-256 hashing to identify caches, test real business scenarios on chatbots, measure immediate gains in latency and costs, produce a caching audit report on your red thread project to visualize professional optimization opportunities.
Build custom caching wrappers in asynchronous Python, integrate Redis as a backend to store LLM responses, apply TTL strategies and intelligent invalidation on concrete business cases, migrate an existing pipeline without major refactoring, measure token consumption reductions via Grafana dashboards, finalize a functional prototype of your red thread project with unit tests for rapid production deployment.
Optimize cache hit rates above 80% on mixed OpenAI and local workloads, hybridize with vector stores for dynamic contextual prompts, implement monitoring with Prometheus to alert on cache misses, resolve pitfalls like variable prompts via fuzzy matching, apply to enterprise use cases such as scalable RAG, refine your red thread project with A/B testing to validate real performance and cost gains.
Deploy your prompt caching solution on Kubernetes with autoscaling, secure caches against sensitive data leaks via encryption and ACLs, integrate CI/CD for automated updates, simulate extreme loads to validate resilience, prepare documentation and handover for IT teams, conclude with the defense of your optimized red thread project, ready for immediate ROI in a certifying enterprise.
The Training Prompt Caching - Optimizing LLM Costs and Latency program is delivered onsite or remote (blended-learning, virtual classroom, remote presence). At Learni, an industry-certified training organization, every program is built to maximize skills acquisition regardless of the chosen format.
The trainer alternates between demonstrative, interrogative and active methods (through hands-on labs and/or scenarios). This pedagogical approach guarantees concrete learning that's immediately applicable at work.
For the smooth delivery of the Training Prompt Caching - Optimizing LLM Costs and Latency program, the following equipment is required:
For intra-company training on a site outside Learni, the client commits to providing all required teaching materials (computers, internet, etc.) for the smooth delivery of the program in line with the prerequisites in the communicated program.
Assessment of skills acquired during the Training Prompt Caching - Optimizing LLM Costs and Latency program is performed through:
Learni is committed to making its programs accessible. All our programs are accessible to people with disabilities. Our teams are available to adapt the pedagogical methods to your specific needs. Please contact us for any adjustment request.
Registration is possible up to 48 business hours before the start of training. All our programs are built for corporate L&D budgets and delivered onsite or remotely.
Before, during, after: we frame the brief, introduce the trainer, tailor the content and measure impact. You stay in control from kickoff to wrap-up.
Each trainer is validated on three criteria: hands-on field expertise, proven pedagogy and alignment with your industry.
30-minute video call between you and the selected trainer to validate the fit, adjust content and clear any final doubts.
No recycled slides. The syllabus is reworked from your real cases: tools, constraints, vocabulary, ongoing projects.
Live evaluations, 30/90/180-day check-ins and a consolidation plan. If the impact misses the mark, we rework it.
A simple promise: you don't pay to discover the trainer on day one. Everything is validated upfront, by you.
 Generative AI & LLMsIndustry-certified
 Security standards & governanceIndustry-certified
 Generative AI & LLMsIndustry-certified
 Generative AI & LLMsIndustry-certified
 Prompt engineeringIndustry-certified
 Prompt engineeringIndustry-certified
 Prompt engineeringIndustry-certified
 Prompt engineeringIndustry-certifiedPrompt engineeringIndustry-certified
 Prompt engineeringIndustry-certifiedGenerative AI & LLMsIndustry-certified
 Generative AI & LLMsIndustry-certified
 Generative AI & LLMsIndustry-certified
 Generative AI & LLMsIndustry-certifiedGenerative AI & LLMsIndustry-certified
 Generative AI & LLMsIndustry-certifiedMachine learningIndustry-certified
 Machine learningIndustry-certified
 Machine learningIndustry-certified
 Machine learningIndustry-certified
 Machine learningIndustry-certified
 Machine learningIndustry-certifiedAutomation & workflowsIndustry-certifiedAutomation & workflowsIndustry-certifiedAutomation & workflowsIndustry-certified
 Automation & workflowsIndustry-certifiedAutomation & workflowsIndustry-certified
 Automation & workflowsIndustry-certified
Available on-site and remotely. Pick your city to see the local training center.
30 minutes with a learning advisor. No commitment. No sales pitch dressed up as a demo.