
Rigorous trainer selection
Each trainer is validated on three criteria: hands-on field expertise, proven pedagogy and alignment with your industry.
- Triple validation: technical, pedagogical, sectoral.
- Minimum rating 4.8/5 over the last 12 sessions.

Describe your need, get a tailored program and a pre-filled quote in 3 min. A 100% free call with an advisor.

1 seat held for the next session
Request a call back and an advisor reaches you within 24 business hours, Monday to Saturday.
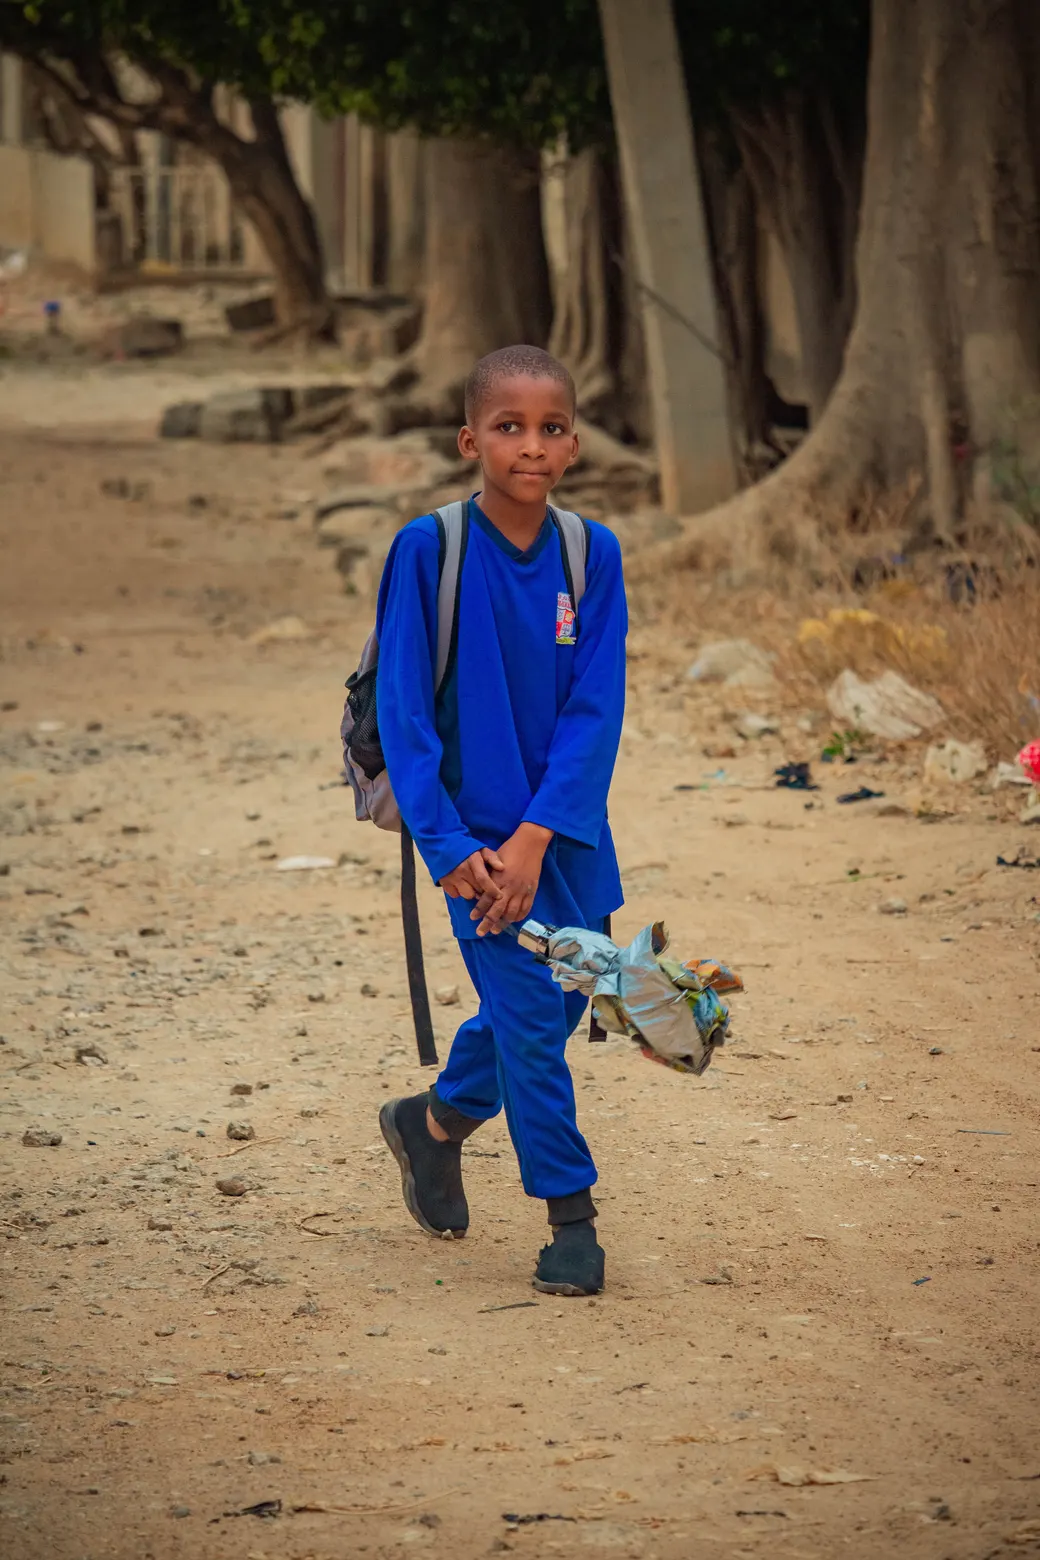
To fight inequalities in access to education, Learni donates a complete school kit to a child in need for every training booked. You build your skills, a child heads back to school.
Founded by engineers and learning experts, Learni's mission is to make high-impact tech training accessible to teams everywhere. We work remotely with organizations across the US and Canada, in your time zone, to help teams upskill fast.
Don't let this gap widen
Without advanced Apache Spark skills, big data pipelines run 4 to 6 times slower, wasting up to 30 000 € annually in unnecessary cloud costs per team.
65% of analytics projects fail due to lack of Spark optimization, causing 25% revenue losses on missed real-time insights.
Untrained data engineers stagnate in their careers while competitors deploy distributed ML 3x faster.
Every quarter without training widens an insurmountable competitive gap in the exploding big data market.
Immediate setup of a distributed Spark cluster in cloud mode, deep dive into Spark SQL for complex queries on terabyte datasets, mastery of the Catalyst Optimizer to accelerate joins and aggregations, creation of custom UDFs in Python/Scala, practical exercises on real enterprise cases such as massive log analysis, tuning of memory and executor parameters for 50% speed gains, production of optimized deliverables ready for production.
Integration of Spark Streaming with Kafka to ingest real-time IoT streams, development of fault-tolerant micro-batches on high volumes, construction of complete MLlib pipelines with distributed feature engineering and scalable models, cross-validation evaluation on clusters, automated deployment via Spark Submit and advanced monitoring with Spark UI/Ganglia, collaborative workshops on enterprise red thread projects, generation of predictive dashboards and scaling plans for immediate ROI.
The Training Apache Spark - Optimizing Big Data Processing program is delivered onsite or remote (blended-learning, virtual classroom, remote presence). At Learni, an industry-certified training organization, every program is built to maximize skills acquisition regardless of the chosen format.
The trainer alternates between demonstrative, interrogative and active methods (through hands-on labs and/or scenarios). This pedagogical approach guarantees concrete learning that's immediately applicable at work.
For the smooth delivery of the Training Apache Spark - Optimizing Big Data Processing program, the following equipment is required:
For intra-company training on a site outside Learni, the client commits to providing all required teaching materials (computers, internet, etc.) for the smooth delivery of the program in line with the prerequisites in the communicated program.
Assessment of skills acquired during the Training Apache Spark - Optimizing Big Data Processing program is performed through:
Learni is committed to making its programs accessible. All our programs are accessible to people with disabilities. Our teams are available to adapt the pedagogical methods to your specific needs. Please contact us for any adjustment request.
Registration is possible up to 48 business hours before the start of training. All our programs are built for corporate L&D budgets and delivered onsite or remotely.
Before, during, after: we frame the brief, introduce the trainer, tailor the content and measure impact. You stay in control from kickoff to wrap-up.
Each trainer is validated on three criteria: hands-on field expertise, proven pedagogy and alignment with your industry.
30-minute video call between you and the selected trainer to validate the fit, adjust content and clear any final doubts.
No recycled slides. The syllabus is reworked from your real cases: tools, constraints, vocabulary, ongoing projects.
Live evaluations, 30/90/180-day check-ins and a consolidation plan. If the impact misses the mark, we rework it.
A simple promise: you don't pay to discover the trainer on day one. Everything is validated upfront, by you.
 Data engineeringIndustry-certified
 DevOps & CI/CDIndustry-certified
 Big dataIndustry-certified
 Data engineeringIndustry-certified
 Big dataIndustry-certified
 Big dataIndustry-certified
 Big dataIndustry-certifiedBig dataIndustry-certified
 Big dataIndustry-certified
 Big dataIndustry-certified
 Data engineeringIndustry-certified
 Data engineeringIndustry-certified
 Data engineeringIndustry-certified
 Data engineeringIndustry-certified
 Data engineeringIndustry-certified
 Data engineeringIndustry-certified
 DevOps & CI/CDIndustry-certifiedDevOps & CI/CDIndustry-certifiedDevOps & CI/CDIndustry-certifiedDevOps & CI/CDIndustry-certified
 DevOps & CI/CDIndustry-certifiedDevOps & CI/CDIndustry-certifiedETL & data pipelinesIndustry-certified
 ETL & data pipelinesIndustry-certifiedETL & data pipelinesIndustry-certified
 ETL & data pipelinesIndustry-certified
 ETL & data pipelinesIndustry-certifiedETL & data pipelinesIndustry-certified
Available on-site and remotely. Pick your city to see the local training center.
30 minutes with a learning advisor. No commitment. No sales pitch dressed up as a demo.