
Rigorous trainer selection
Each trainer is validated on three criteria: hands-on field expertise, proven pedagogy and alignment with your industry.
- Triple validation: technical, pedagogical, sectoral.
- Minimum rating 4.8/5 over the last 12 sessions.

Describe your need, get a tailored program and a pre-filled quote in 3 min. A 100% free call with an advisor.

25,719 programs · 25 countries
Every program built with a dedicated engineer






Companies: Aptar, ArcelorMittal, Equans, EDF, Ubisoft and Microsoft.
Discover the principles of Vision-language models through theoretical and practical modules, exploring CLIP, BLIP, and Flamingo with multimodal datasets like LAION or COCO. Perform joint vision-text encoding exercises, analyze multimodal transformers, and generate your first cross-modal embeddings for classification tasks, all in interactive remote sessions for rapid mastery of essential skills.
Dive into fine-tuning VLMs on real business cases, use Hugging Face Transformers to adapt pre-trained models to your custom visual and textual data, implement LoRA and QLoRA techniques to optimize resources, test on benchmarks like VQA or captioning, generate performance reports, and deploy a functional prototype ready for professional integration.
Explore advanced Vision-language model applications for visual search, description generation, and zero-shot learning. Code pipelines with TensorFlow for retrieval and PyTorch for generation, work on real datasets like Visual Genome, evaluate with FID and BLEU metrics, collaborate in live sessions to solve business challenges, and deliver a complete optimized notebook.
Integrate Vision-language models into professional MLOps workflows using Docker, Kubernetes, and MLflow. Set up inference servers with TensorRT and ONNX, automate CI/CD pipelines for multimodal model monitoring, test latency on cloud GPUs, manage enterprise model versions, and produce an end-to-end deployment with performance dashboards.
Complete a capstone project on a business application like medical image analysis or e-commerce using Vision-language models. Optimize for efficiency with distillation and pruning, integrate secure APIs, evaluate business impact via simulated ROI, present your solution in a professional pitch, receive certifying feedback, and leave with a concrete portfolio to boost your multimodal AI career.
The Training Vision-language models - Mastering Multimodal AI in the Enterprise program is delivered onsite or remote (blended-learning, virtual classroom, remote presence). At Learni, an industry-certified training organization, every program is built to maximize skills acquisition regardless of the chosen format.
The trainer alternates between demonstrative, interrogative and active methods (through hands-on labs and/or scenarios). This pedagogical approach guarantees concrete learning that's immediately applicable at work.
For the smooth delivery of the Training Vision-language models - Mastering Multimodal AI in the Enterprise program, the following equipment is required:
For intra-company training on a site outside Learni, the client commits to providing all required teaching materials (computers, internet, etc.) for the smooth delivery of the program in line with the prerequisites in the communicated program.
Assessment of skills acquired during the Training Vision-language models - Mastering Multimodal AI in the Enterprise program is performed through:
Learni is committed to making its programs accessible. All our programs are accessible to people with disabilities. Our teams are available to adapt the pedagogical methods to your specific needs. Please contact us for any adjustment request.
Registration is possible up to 48 business hours before the start of training. All our programs are built for corporate L&D budgets and delivered onsite or remotely.
Founded by engineers and learning experts, Learni's mission is to make high-impact tech training accessible to teams everywhere. We work remotely with organizations across the US and Canada, in your time zone, to help teams upskill fast.
Before, during, after: we frame the brief, introduce the trainer, tailor the content and measure impact. You stay in control from kickoff to wrap-up.
Each trainer is validated on three criteria: hands-on field expertise, proven pedagogy and alignment with your industry.
30-minute video call between you and the selected trainer to validate the fit, adjust content and clear any final doubts.
No recycled slides. The syllabus is reworked from your real cases: tools, constraints, vocabulary, ongoing projects.
Live evaluations, 30/90/180-day check-ins and a consolidation plan. If the impact misses the mark, we rework it.
A simple promise: you don't pay to discover the trainer on day one. Everything is validated upfront, by you.
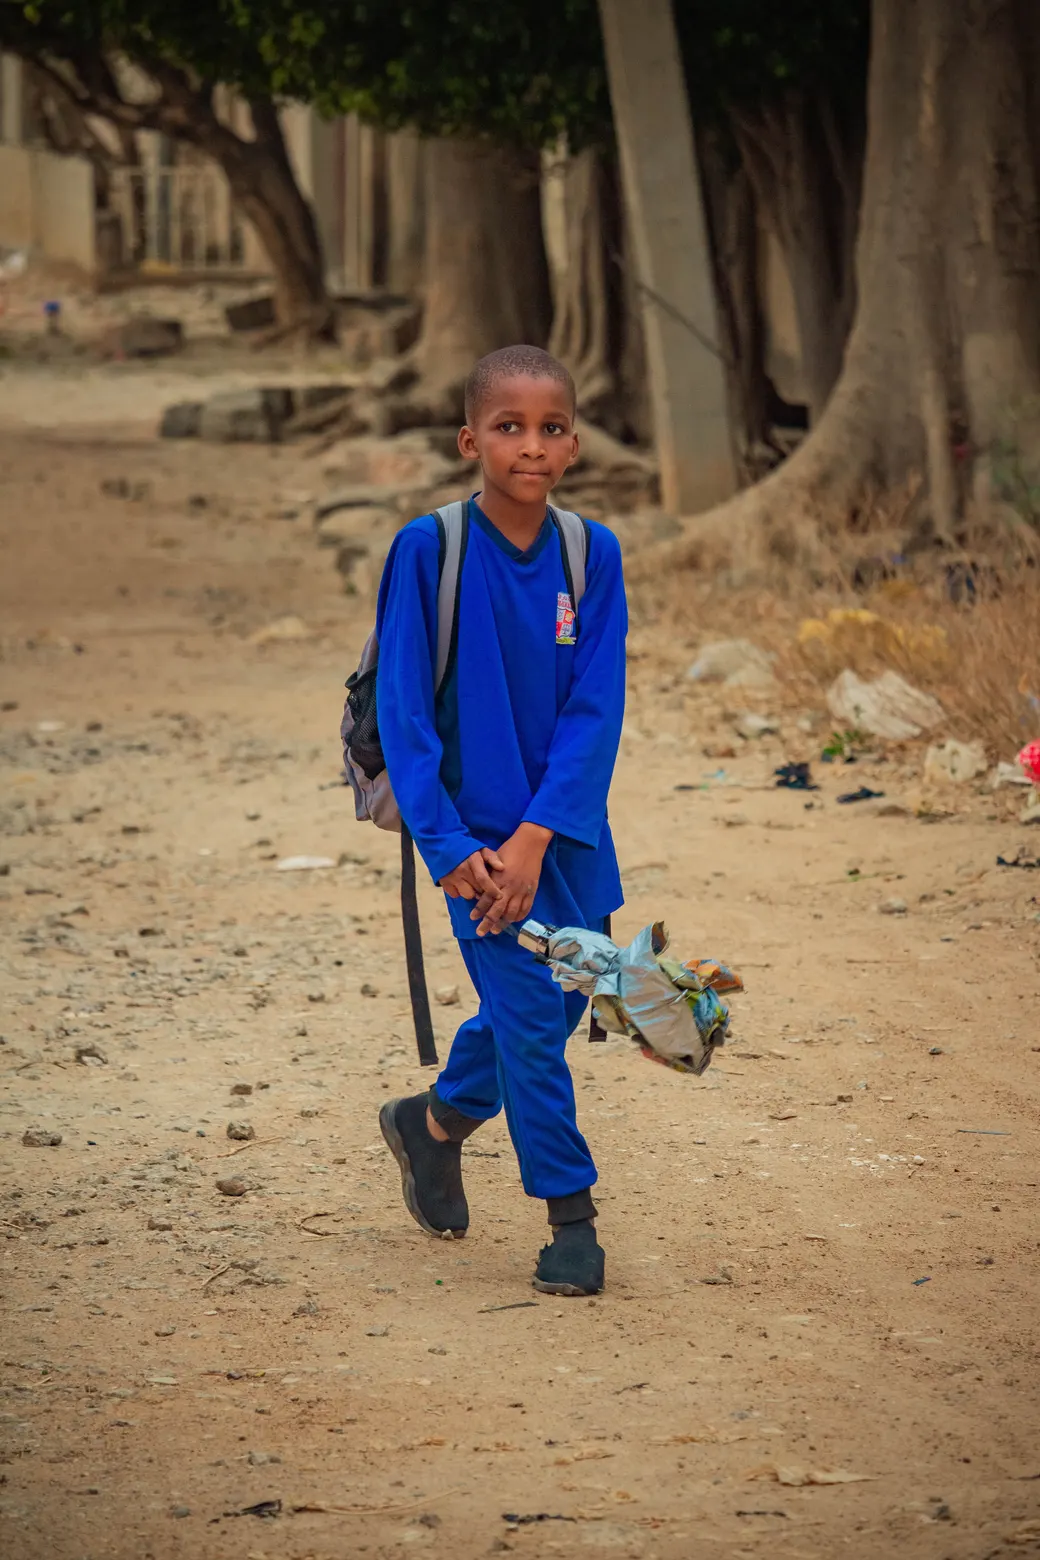
To fight inequalities in access to education, Learni donates a complete school kit to a child in need for every training booked. You build your skills, a child heads back to school.
30 minutes with a learning advisor. No commitment. No sales pitch dressed up as a demo.
 Generative AI & LLMsIndustry-certified
 Generative AI & LLMsIndustry-certified
 Generative AI & LLMsIndustry-certified
 Generative AI & LLMsIndustry-certified
 Generative AI & LLMsIndustry-certified
 Generative AI & LLMsIndustry-certifiedDeep learningIndustry-certifiedDeep learningIndustry-certified
 Deep learningIndustry-certified
 MLOps & AI industrialisationIndustry-certifiedMLOps & AI industrialisationIndustry-certifiedMLOps & AI industrialisationIndustry-certified
 Machine learningIndustry-certified
 Machine learningIndustry-certifiedMachine learningIndustry-certified
Available on-site and remotely. Pick your city to see the local training center.
We will call +1 (United States) 🇺🇸 — change the country code on the left if your number is from elsewhere.